What Training Dataset Transparency Mandates Hide
Will Orr / Oct 29, 2026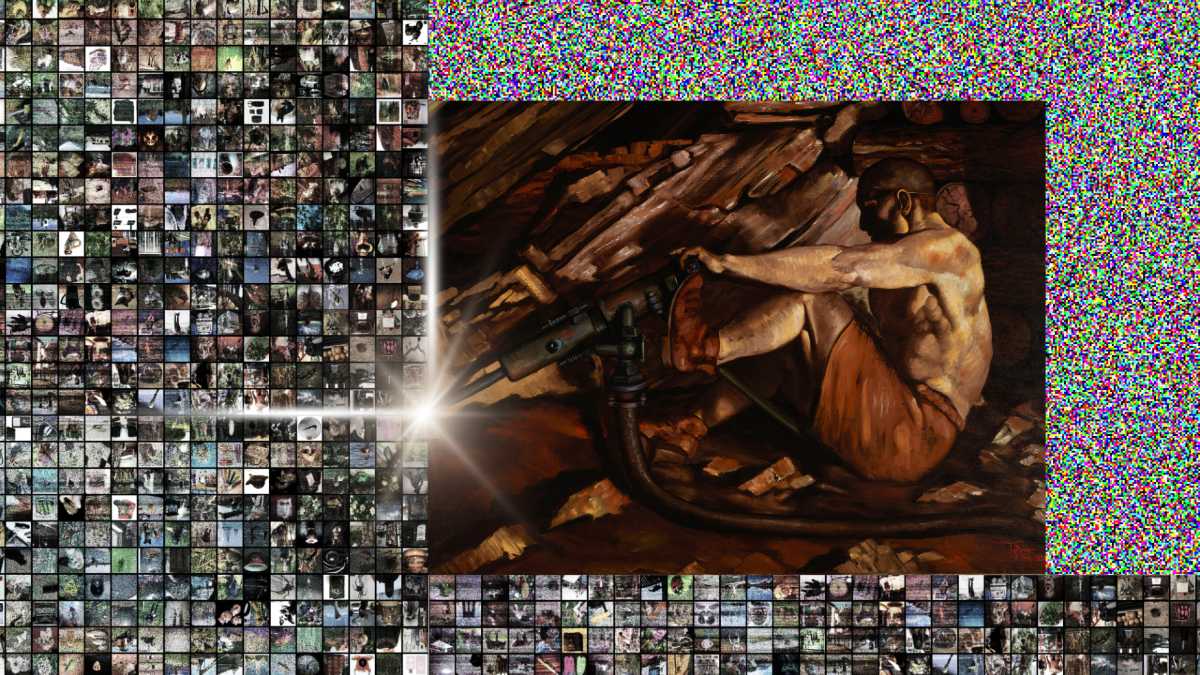
Primitive Accumulation by Daniela Zampieri / Better Images of AI / CC by 4.0
A common assumption in AI governance is that greater transparency regarding the composition of the datasets used to train large language models will enable governments, researchers, and other stakeholders to demand greater accountability from the companies that build AI systems. Training datasets are often a driving cause of AI related harms, such as bias, discrimination, and the erosion of digital rights. The intention of transparency requirements is to provide copyright holders, privacy advocates and critical AI researchers information about the data used to train AI models, so that they can verify whether their interests were protected, and hold AI companies to account. In doing so, dataset transparency disclosures can arm consumers (both individuals and companies) with the necessary information to choose which AI system is right for them.
This perspective has been adopted by multiple state, national and international jurisdictions. Most notably, California and the European Union have both passed laws requiring frontier AI companies to provide summaries of their training dataset composition. But many stakeholders focused on governing AI in the public interest may not sufficiently understand or appreciate the limits of current training dataset transparency mandates. This piece aims to demystify what existing dataset transparency mandates actually produce, detail critical processes they fail to reveal, and then point towards productive avenues for pursuing meaningful transparency about datasets that can better enable accountability.
It is important to understand that uncovering the contents of training datasets alone is insufficient to enable meaningful accountability. Knowing what is included in a training dataset provides little insight into why it was included—let alone how it can be contested. And the rationales behind data practices ultimately shape whose data is included, whose interests are protected, and who bears the burden of dataset-related harms. Achieving accountability requires understanding how these artifacts were made, and the rationale behind dataset creation practices that are often considered banal or perfunctory.
Existing training dataset transparency statements are vague and ineffective
California's Training Data Transparency Act (TDTA), which came into effect Jan. 1, 2026, mandates that developers of generative AI systems provide a “high-level summary” of training dataset composition across twelve categories, from the types of data included to the presence of private data or copyrighted material, how the data was acquired, any cleaning, filtering or manipulation processes, and the presence of synthetic data. The European Union's Artificial Intelligence Act, which recently came into effect, also includes a requirement that developers of generative AI systems publish a “sufficiently detailed summary” of the contents of their training datasets. However, compliance with these mandates has been far from straightforward. Copyright litigation against AI developers has incentivized opacity about training dataset creation and contents. In March, a California federal court denied xAI’s legal challenge of the TDTA. The company argues the law forces it to reveal trade secrets in violation of the Fifth Amendment and compels speech in violation of the First Amendment—a decision that xAI is appealing.
Early compliance with these regulations has been broad and vague at best. OpenAI's disclosure, for example, notes that training datasets consist of publicly available internet sources, third-party licensed datasets, synthetic data, and human-labelled and user data. They do not explicitly notify copyright holders of whether their property has been included, nor whether private information has been captured. Moreover, disclosure statements do not offer a way to evaluate or compare how training datasets might disproportionately affect certain populations. Existing disclosure statements resemble what Evelyn Douek calls "transparency theater" that amounts to performative compliance, rather than serving as an engine of meaningful accountability. In fact, Stanford's Foundation Model Transparency Index found in December 2025 that training data composition remains among the most opaque aspects of AI systems, particularly on how data is acquired and its characteristics.
However, enforcing more granular training dataset transparency in its current formulation may not produce meaningful accountability for AI systems and their foundations. Existing dataset disclosure statements provide vague allusions to the origins, purpose, scale and contents about training datasets. They provide very little insight into why specific dataset creation processes were chosen. Datasets are created through iterative and ad hoc processes, with consequential decisions cascading throughout the model development pipeline. But existing dataset documentation practices retroactively reconstruct these processes as a clean, linear narrative that obfuscates how these decisions were made in practice. In doing so, they erase the possibility that these decisions were ever contestable. So long as dataset disclosures fail to detail the processes and rationale behind training dataset construction, they will fail to provide meaningful accountability.
Transparency disclosures hide key practices and judgement calls
What goes into a training dataset is a consequential decision, but far from the only consequential one. Exactly how or why data is collected and processed remains opaque. For instance, frontier labs like Anthropic, Google, and OpenAI all operate their own web crawlers, which collect pages of web text for training purposes. We don’t know how the crawlers prioritize which pages to collect, nor do we know the methods by which they discover new pages to crawl. Existing research into web crawlers demonstrates how these decisions can lead to systems that overrepresent older, well-linked, English-language institutional sources. Web data is just one aspect of training datasets. The composition of licensed, labelled and user-generated datasets, and how they were acquired, labelled or evaluated for suitability, remain functionally undisclosed. So are the processes through which synthetic data is generated for training purposes. Each of these decisions in the dataset creation pipeline impacts the contents of training datasets, and the rights of the people represented within them. Yet, as these processes remain opaque, so too do the harms they produce.
Existing disclosures of dataset cleaning processes are also abstract overviews. Unsealed court documents provide rare insight into the processes through which Meta engineers filter training datasets. Through processes known as experimental ablation, multiple versions of training datasets are created using different filtering heuristics, which are then compared by training models and assessing performance on standardized benchmark evaluations. For example, Meta engineers replaced some of their existing training data with science and technology books, and fiction books from a pirated library and compared their performance. Rather than creating "clean" or "high quality" datasets, these processes utilize data processing to achieve superior technical performance. Training dataset ablation has become common practice in the AI industry, with one Meta engineer claiming to perform over 100 ablations during the development of LLaMa 4. These details are missing from public transparency statements.
Under the paradigm of experimental ablation, decisions about what good data is, and how training datasets should be constructed are deferred to the benchmarks used to evaluate their quality. This creates a cycle of benchmark recursion in which benchmark datasets influence the kinds of data deemed high quality in the first place. This is particularly concerning as the benchmarks used to verify training dataset quality are themselves flawed artifacts. For example, one benchmark that Meta uses to compare training dataset composition, Hellaswag, has been found to include ungrammatical prompts (31% of questions), nonsense incorrect options (85% of questions) and multiple correct answers (8% of questions), with researchers arguing that it should not be used for evaluation. Knowing which benchmarks were used to filter training datasets and why is precisely the kind of information that transparency mandates should surface to enable improved accountability and consumer protections. These are essentially model governance decisions, shaping the very foundations of AI systems, their capabilities and their social impacts. But these decisions and their rationale remain unavailable for public scrutiny.
Meaningful transparency requires detailing how and why datasets are made
Tracing data acquisition and cleaning pipelines demonstrates that dataset creators make real and consequential decisions without clear right answers, often in gray areas without formal rules, and under intense competitive pressure to quickly develop better models. Decisions like web crawler settings, choosing benchmarks to evaluate dataset quality, or selecting a data cleaning process all impact the kinds of data included in training, and ultimately how these datasets shape AI systems. Transparency statements that summarize what is included in a training dataset do not communicate how these datasets were created, or why certain decisions were made — the on-the-ground decisions that actually impact the people behind the data. Meaningful transparency in dataset creation therefore requires going beyond simply summarizing the technical inputs of AI training, to document the processes through which these datasets are created, and the rationale behind why such decisions were made. In other words, it requires not just seeing inside datasets, but “looking across” datasets as systems of “invisible decisions” made within tech companies. Such disclosures would rely on at least four mechanisms:
- Governments issuing or updating transparency mandates should include requirements that regulated companies publicly disclose the criteria they use to determine dataset composition and assess dataset quality. This includes disclosing the benchmarks and evaluation criteria used to infer dataset quality. If benchmarks and model evaluations increasingly define "good data" and shape dataset practices, they should be open to public and researcher scrutiny, not treated as neutral, unexaminable infrastructure sitting behind the disclosure.
- Companies should maintain a running version log and decision rationale at each stage of dataset construction. Rather than reconstructing a clean retrospective summary of dataset construction, companies should record details such as how data collection and filtering pipelines were decided, why, and under what constraints. Open-source developers already provide these kinds of details in their dataset documentation, showing that these disclosures are feasible and effective — such as enabling meaningful, controlled comparisons between dataset creation methodologies. Whether or not these kinds of logs and compilation of decision rationales are ultimately mandated by law or regulation, they should emerge as company best practices that can help facilitate meaningful public and researcher understanding.
- Relatedly, governments should require and/or incentivize the opening up of dataset acquisition and processing pipelines to independent auditors. Providing third party auditors access to dataset creation pipelines and decision rationales can satisfy calls of proprietary information and anti-competition regulation, while keeping AI companies accountable for their decisions. An Illinois law signed in July requires large frontier AI developers to subject their models to external audits to evaluate catastrophic risk, but makes no mention of auditing training dataset composition or creation. Implementing guidelines and new legislation should make clear that auditors should have access to meaningful information about the process and rationales for dataset creation. Relatedly, ensuring the genuine independence of “third-party” auditors is an important short- and long-term goal. Required audits (and this kind of specificity about what auditors should be able to see in assessing safety, reliability, and bias) are important both for commercially deployed models and for government procurement.
- The mechanisms outlined in above should not be shaped in the abstract by policymakers alone, but should emerge from consultation with dataset creators and practitioners. This kind of consultative process can help ensure that transparency requirements are built around the technical and institutional realities of how datasets are made in practice, and surface the most impactful and least well-understood processes.
This is not an argument against AI companies releasing training datasets for researchers and the public alike to scrutinize. The point is that policymakers, researchers, and civil society should expand their conception of transparency about datasets. Knowing what is in a dataset alone cannot tell us how it was built, why certain data was included, or what was left out and why. These are consequential model governance decisions that affect people present in datasets, and their disclosure should not be limited to extraordinary circumstances such as copyright litigation. Transparency mandates will be ineffective at building accountability while these practices, standards and rationales shaping AI systems remain hidden.
Authors